Text Generation WebUI (by oobabooga) is a popular open-source web interface for running large language models locally. It supports GGUF models via llama.cpp, Hugging Face Transformers, ExLlamaV2/V3 and more, with a chat interface, an OpenAI-compatible API and LoRA training.
Table of Contents
Requirements
| Minimum | Recommended | |
|---|---|---|
| GPU | None (CPU with GGUF) or NVIDIA 8 GB | NVIDIA RTX 16–24 GB |
| RAM | 16 GB | 32 GB+ |
| Disk | 20 GB+ | SSD with space for models (5–50 GB each) |
How to Install Text Generation WebUI
Option 1: Portable build (easiest)
Download a portable release for your OS from the GitHub releases page, extract it and run it. Portable builds use llama.cpp with GGUF models and need no installation.
Option 2: One-click installer
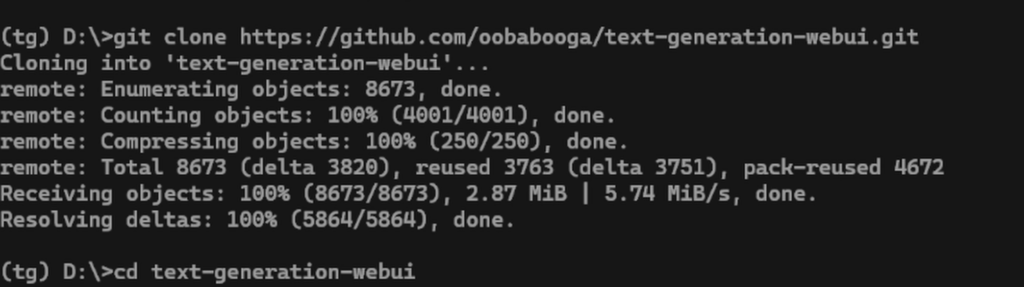
git clone https://github.com/oobabooga/text-generation-webui
cd text-generation-webui
# Windows
start_windows.bat
# Linux
./start_linux.sh
# macOS
./start_macos.sh
The script installs Miniconda, PyTorch and all dependencies, and asks which GPU you have. When it finishes, open http://127.0.0.1:7860.
Load a Model
- Open the Model tab.
- Paste a Hugging Face repo, for example a GGUF build of Qwen or Gemma 4, and click Download.
- Select the model, choose the loader (llama.cpp for GGUF) and click Load.
- Go to the Chat tab and start talking.
Enable the API
Start with --api to get an OpenAI-compatible endpoint on port 5000, so other AI apps can use your local model.
Troubleshooting
- Model too slow: use a smaller quantization (Q4_K_M) or offload more layers to the GPU.
- CUDA out of memory: lower context length or pick a smaller model.
- Installer errors: delete the
installer_filesfolder and run the start script again.
Run It on a GPU Server
No powerful GPU at home? You can run Text Generation WebUI on a rented GPU server instead. RunPod and Vast.ai have text-generation-webui templates. For a fixed monthly price, GPU Mart (RTX A4000 VPS from $119/month, RTX 4090 $409/month) and HOSTKEY (RTX 4090 from €279/month) offer dedicated servers you can keep running 24/7.
FAQ
No, GGUF models run on CPU, but a GPU is much faster.
Most open LLMs: Llama, Qwen, Gemma, Mistral, DeepSeek distills and more, in GGUF, safetensors or EXL2/EXL3 formats.
Conclusion
Text Generation WebUI is a powerful all-in-one interface for local LLMs. See also how to run Oobabooga and LM Studio.